Problem
Large volumes of physical and unstructured documents required manual classification and archival processing. The process was slow and error-prone and increased operational and compliance risk.
Solution
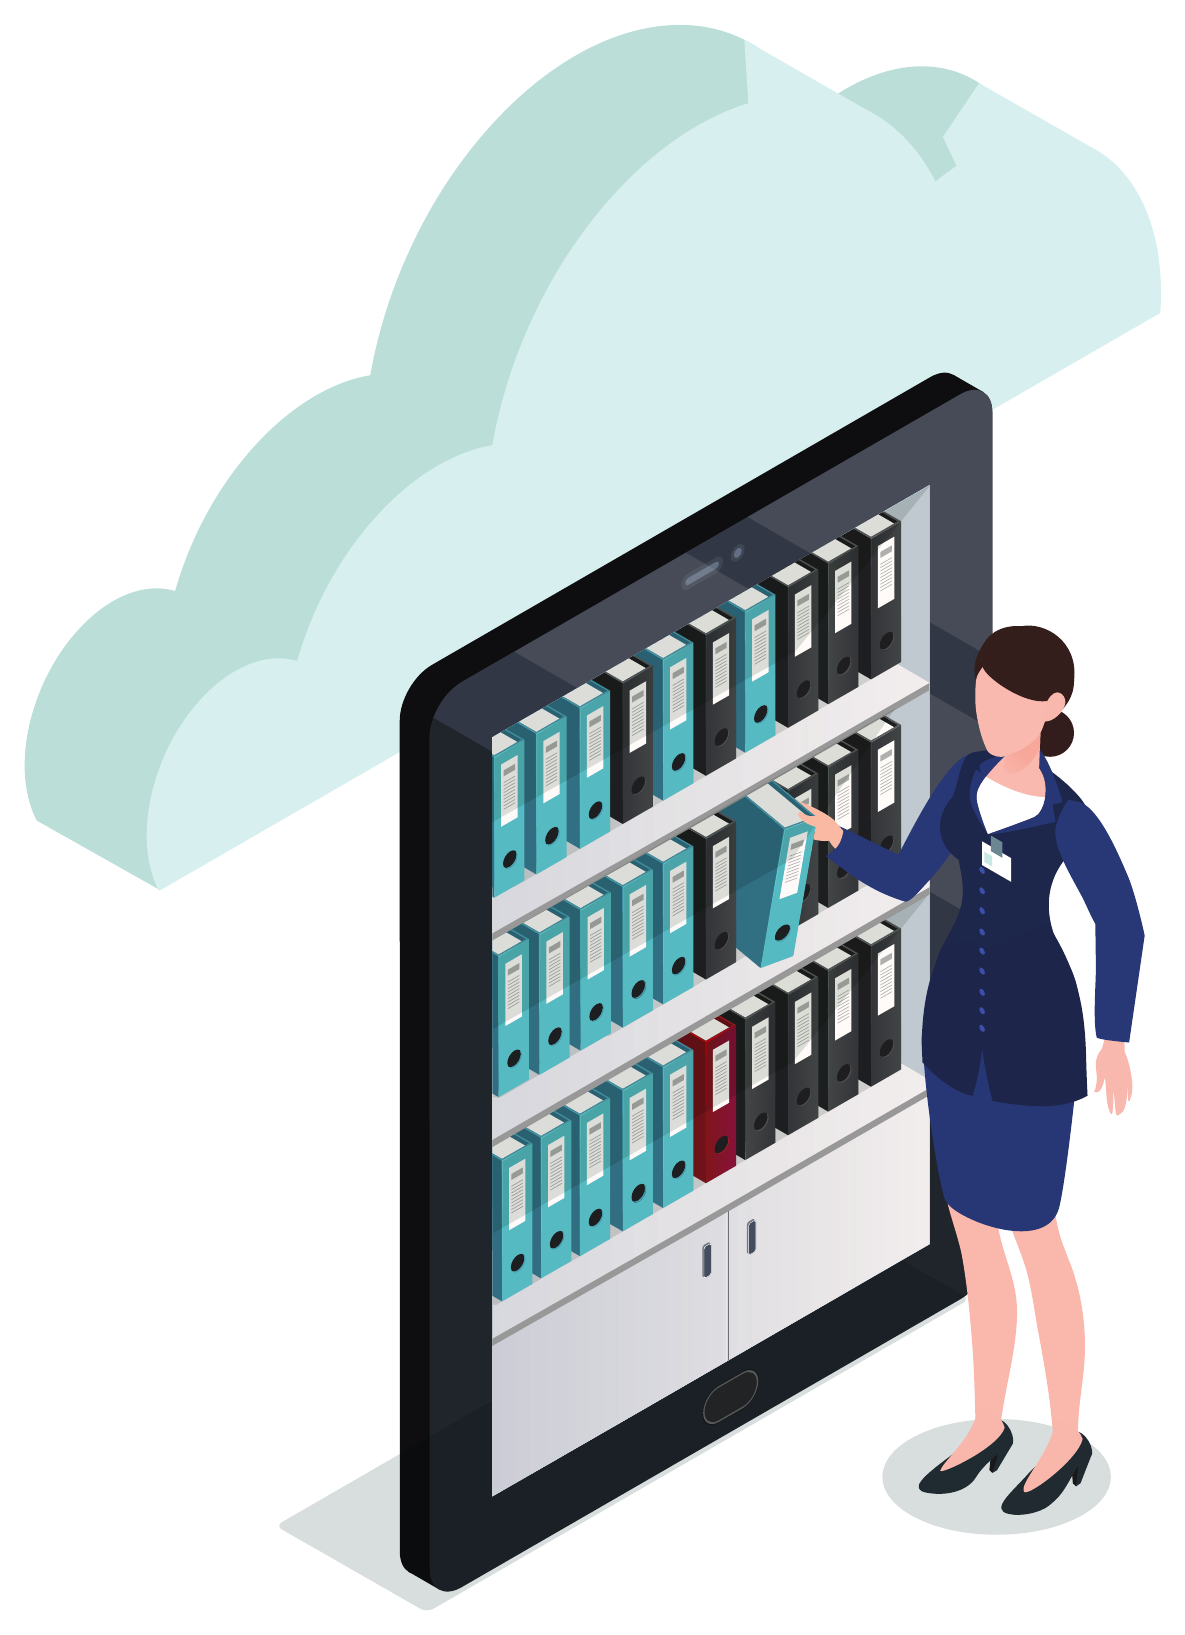
A machine-learning based system digitizes incoming documents and classifies them from learned formats and structures. Recognized document types can be routed into the digital archive with structured metadata, reducing the amount of manual classification required in the process.
Technical flow
01Document
02Digitization
03ML Classification
04Metadata
05Digital Archive
Technology and architecture components
Machine LearningDocument ProcessingClassificationDigital ArchiveEnterprise Integration